
Switch AI Trust and ROI: A Cost-per-Outcome Pilot for Kenyan SMEs
Switch AI Trust and ROI for Kenyan SMEs: measure cost per verified outcome, review risks and test one agent before scaling.
UniqueTechCamp Editorial
Lead Systems Architect • UniqueTechCamp Engineering Unit
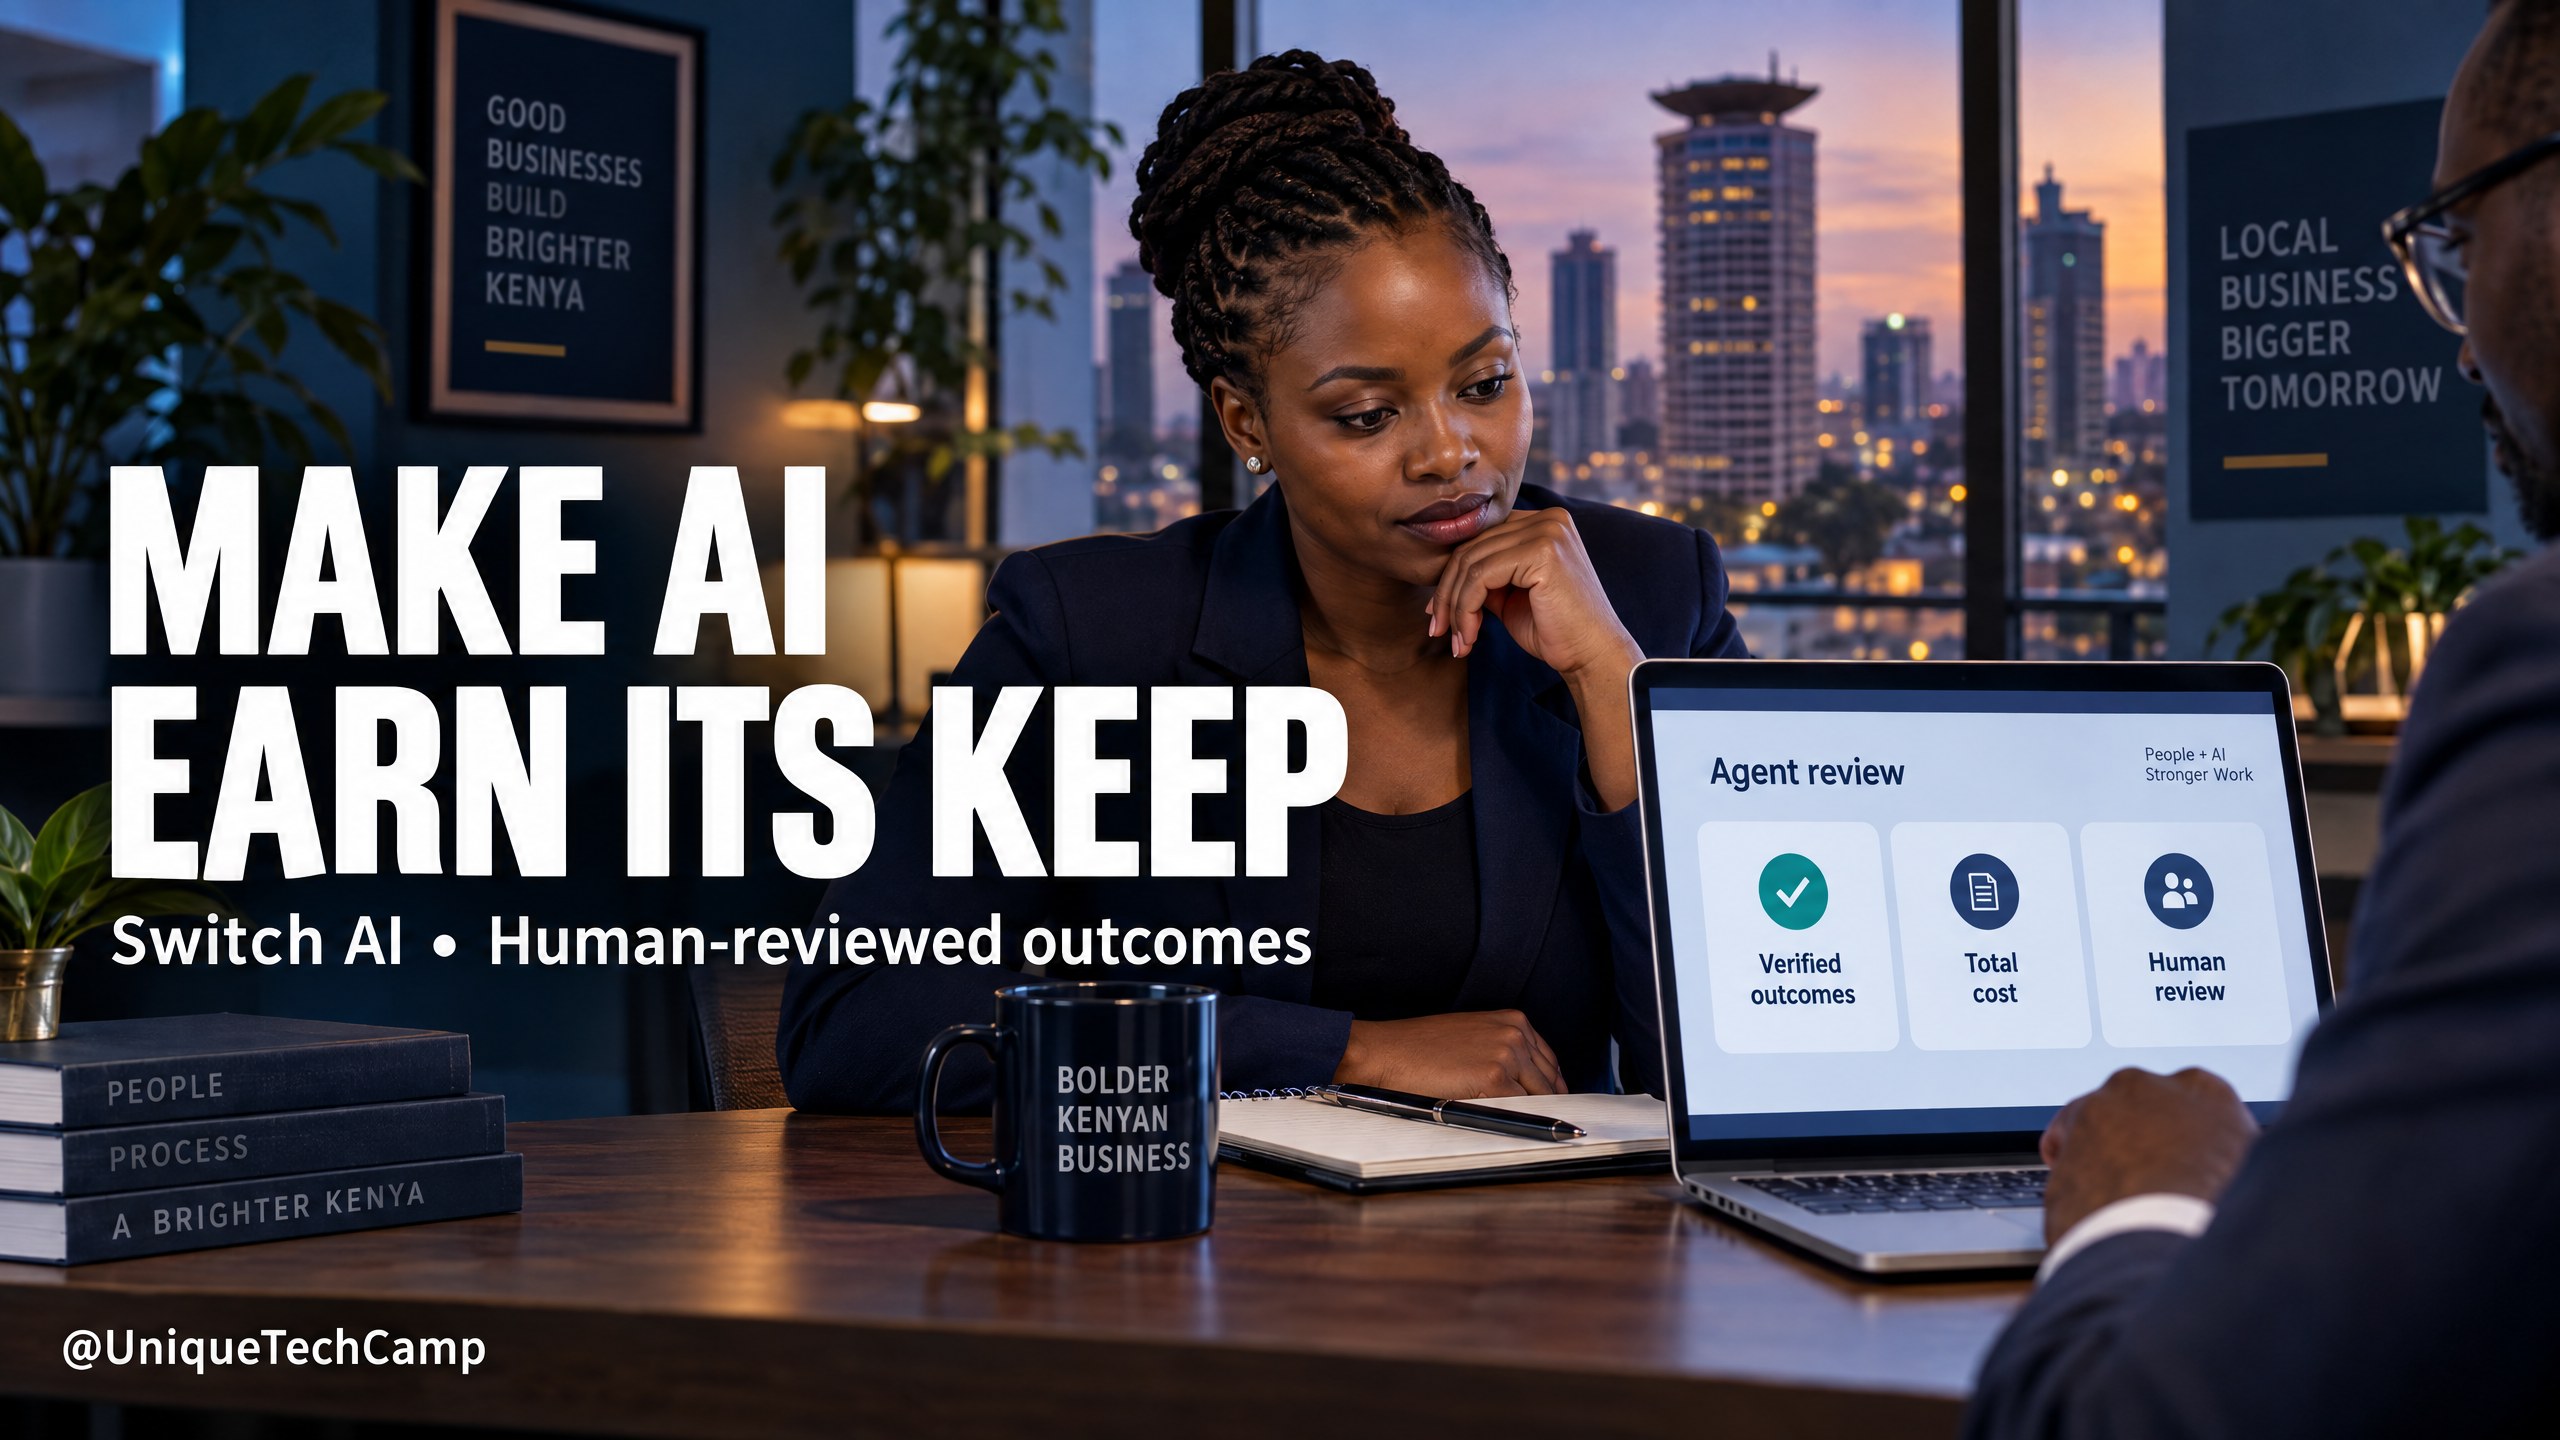
For a small Kenyan business, an AI assistant can appear busy long before it proves useful. It may read messages, draft replies, search a knowledge base and hand work to another tool. None of that, by itself, proves that a customer received a correct answer, that a booking was properly handled or that a team member can safely rely on the result.
The practical question is therefore not “How many AI actions did we buy?” It is “What verified outcome did each action help us achieve, at what total cost, and with what human oversight?” That shift matters for an owner watching cash, customer trust and staff time. It also gives a smaller organisation a sensible way to test agentic AI without treating a vendor dashboard as an accounts ledger or a safety certificate.
On 19 October 2026, SandboxAQ’s announcement about Switch AI’s trust and return-on-investment expansion ↗ described a broader control and measurement direction. The rooms capability had already launched in August 2026, so this is not a story about a brand-new chat room. It is a useful prompt for business owners to ask whether monitoring, model choice and outcome accounting solve a real operational problem.
What changed, and what did not?
Switch AI ↗ presents a place where people and agents can work with common context across Slack, Teams and Discord. The 19 October announcement puts extra emphasis on trust and ROI: seeing the agents, models, tools and code in an organisation’s inventory; testing agents before release; applying controls during operation; recording approvals; and examining the cost of an agent in relation to its work.
That distinction is important. A pre-release test involving prompt-injection scenarios is an advertised testing capability, not independent proof that an agent is safe in every setting. Runtime guardrails and an approval record can make decisions easier to inspect, but they do not guarantee regulatory compliance, perfect detection or the absence of a harmful instruction. A responsible pilot keeps a person accountable for the business decision.
The product’s Trust overview ↗ describes inventory visibility, tests and runtime controls. Its ROI overview ↗ describes per-agent cost and outcome analysis, including recommendations about model choice, unused tools, answer length and caching. The current recommendation emphasis is lower cost. Performance improvements are described as coming, so a business should not assume that autonomous quality improvement is already available. Retry and loop optimisation are sensible areas to watch, not features an owner should promise to customers before confirming the entitlement and behaviour.
The announcement is also not a public price list. The Switch AI get-started page ↗ refers to Rooms as free and open source for download, but that should not be read as proof that Trust and ROI have a free production plan, unlimited usage or a particular support arrangement. There is no verified public paid price or set of free-plan limits to use in a Kenyan budget. Ask for a written quote and confirm entitlement, integration limits, data exports, retention, support, currency and tax treatment before committing. Kenyan availability is not explicitly guaranteed by the material described here.
Does your SME need a monitoring platform?
Possibly not at first. A human ledger can be the right starting point. A spreadsheet or shared log can record the date, request type, agent used, human reviewer, final outcome, rework and cost assumptions. For a small team with one low-risk workflow, that simple record may reveal more than a sophisticated screen full of activity.
A monitoring platform becomes more compelling when there are several agents, changing models, multiple tools or a growing need to explain who approved what. It can help an operator see a live inventory and compare work across agents rather than reconstructing the story from scattered messages. The sensible decision is not platform first; it is an agreed outcome definition first, followed by a short comparison between the human ledger and the product’s advertised controls.
A practical cost-per-outcome pilot
Choose one narrow workflow. A support agent that can read a help centre and draft a response is safer to start with than an agent allowed to issue refunds, change a customer record or send an unrestricted payment instruction. The agent might be read-only at the beginning and handle a small set of questions. A person reviews every response before it leaves the business.
1. Inventory the work and permissions
Write down the agent’s purpose in ordinary language: for example, “find the relevant delivery policy and draft a reply for a reviewer”. List the model, tools, data sources, channels and code that can be involved. Give the agent the smallest useful permission set. If it only needs to retrieve policy text, it should not also be able to edit orders or invite other agents.
Record the human owner, escalation route and approval point. A control is useful only when a named person understands it and can stop the workflow. An inventory also makes it easier to notice a forgotten tool or an old connection after the pilot changes.
2. Define a verified resolution
Do not count chats, tokens, tool calls or cheerful “done” messages as outcomes. A verified resolution is an agreed business result checked by a person against a rule. For support, it could mean that the answer cites the current policy, addresses the customer’s question, contains no invented promise and is approved or corrected before sending.
For lead handling, a verified outcome might mean a lead has been classified against written criteria and passed to a salesperson for review. It is not a sale promise. For an internal workflow, it could mean a complete draft is attached to the right case with required fields present. Write the pass conditions before looking at results, otherwise the definition will quietly move to make a weak result look successful.
3. Establish the manual baseline
Measure how the team handles equivalent requests today. Capture actual review time, correction time, materials and any software cost that would remain if the AI were removed. Use comparable work: a difficult request should not be compared with an easy AI example. Note quality failures and escalations, not just speed.
Do not double-count labour. If a staff member’s review time is already included in the cost of a manual resolution, do not add the same time again as a supposed saving. Likewise, an hour that becomes available is not automatically cash profit. It may create capacity, improve service or allow the owner to do higher-value work; those benefits should be described separately from money actually saved.
4. Test with synthetic data and deliberate attacks
Begin with invented customer names, dummy order references and synthetic policy records. Test ambiguous questions, missing information, conflicting instructions and attempts to make the agent reveal hidden instructions. Include prompt-injection cases because an instruction in retrieved content or a message may try to override the workflow. Ask whether the agent pauses, gives a safe explanation and sends the case to a person.
Keep a test record with the input, expected behaviour, observed behaviour, reviewer and decision. Passing a test does not certify the live service. Before production use, confirm what data is retained, who can access it, where it is processed and how it can be exported or deleted. Before commissioning implementation, bring this inventory and synthetic test pack to UniqueTechCamp ↗ to scope a bounded automation pilot with clear human approval points.
5. Count the whole cost
Use an all-in pilot figure: human review, hosting, model usage, platform access, setup and necessary integration work. An ROI view that counts only model calls can make an attractive but incomplete claim. Separate recurring cost from one-off implementation effort. If a supplier quote is still pending, label the model as hypothetical rather than filling the gap with an invented price.
Here is an illustrative calculation, not a Switch AI quote and not a claim about product availability. Suppose a trial’s all-in cost is KSh6,000, including human review, hosting, LLM usage and platform cost, and the team records 120 human-verified resolutions. The cost per verified resolution is KSh50 per verified resolution: KSh6,000 divided by 120. The result is meaningful only if those resolutions meet the same quality bar as the manual baseline. It is not a claim that 120 resolutions have a monetary value of KSh50 each, nor a forecast of profit.
Compare like with like. If the manual process produces a correct, approved resolution, compare it with a correct, approved AI-assisted resolution. Platform self-reporting can help organise evidence, but the owner’s outcome ledger and sample review remain the validation. Keep the calculation understandable enough that a non-technical manager can challenge every line.
6. Change one thing after quality checks
Once the quality sample is accepted, test one cost lever. It might be a less expensive model for straightforward questions, removal of an unused tool, shorter answers or caching repeated information. Change one lever so that the effect is visible. If quality falls, restore the previous setting. A lower bill is not an improvement if it creates more corrections, complaints or unsafe escalations.
Do not treat a recommendation as an instruction. Ask what evidence supports it, which requests it covers and whether the change affects privacy, response accuracy or review effort. Keep a before-and-after note, including exceptions. This is where a trust record and an ROI record should meet: the cheapest path is acceptable only when it still meets the owner’s chosen quality and safety threshold.
7. Review after 30 days and decide clearly
Set a 30-day review date before launch. Continue if the workflow delivers the agreed verified outcomes, the full cost is understood, reviewers can see and correct failures, and permissions remain appropriate. Stop or redesign if the agent invents policy, leaks data, bypasses approval, produces too much rework or cannot provide a dependable record of its actions.
The threshold belongs to the business owner, informed by the workflow’s risk. There is no universal number that makes an AI pilot safe or profitable. A customer-support draft may tolerate a different correction pattern from a payroll or clinical workflow. Put the stop rules in writing and give reviewers authority to pause the agent without waiting for a vendor response.
Trust, privacy and Kenyan operating reality
Kenyan businesses should treat data handling as part of the pilot, not a footnote. The Kenya Data Protection Act text ↗ sets principles including lawful purpose, minimisation, security and rules relevant to transfers outside Kenya. This article offers operational guidance, not legal advice. Ask the organisation’s adviser to assess the actual workflow and data categories.
Do not assume that the SandboxAQ website privacy policy ↗, which states a website scope and an August 2026 date, is a product data-processing agreement. It should not be used as evidence that agent telemetry is covered. Request product terms and a DPA, then ask specifically about retention, training use, data location, access controls, subprocessors, deletion and exports. Keep real customer data out until the answers and your lawful basis are clear.
In a commercial conversation, ask for the exact Trust and ROI entitlement, supported integrations, service levels, incident process and tax treatment. Ask how approval records can be downloaded and how long logs remain available. Ask which controls are configurable by the owner and which are vendor-operated. A written answer is more useful than a general assurance that the platform is trustworthy.
What good business value looks like
A successful pilot may lower the cost of a verified resolution, reduce avoidable rework or let a small team handle a reliable volume of enquiries without lowering service quality. It may also improve confidence: staff can see when the agent used a tool, when a human approved a response and where the system stopped. These are potential gains, not guaranteed outcomes.
Reliability and capacity can support growth when customers receive consistent, reviewed help and staff have more room for judgement. But growth is a business result that must be demonstrated in the owner’s records, not inferred from an agent’s activity count. If the workflow creates new review work or unresolved exceptions, the apparently cheap automation may be expensive in practice.
Frequently asked questions
Is Switch AI the same as an AI chatbot?
No. The described proposition covers people and agents sharing context, with trust and ROI controls around an agentic workforce. The Switch AI ↗ platform is broader than a chatbot. A chatbot may be one interface, but the pilot should focus on a defined business outcome rather than the label.
Can a Trust dashboard prove that an agent is safe?
No. Inventory, pre-release tests, runtime guardrails and approval records can support oversight. They are advertised vendor functions, not independent proof of safety, guaranteed compliance or perfect prompt-injection detection. Keep human review and stop rules.
Is Rooms free, and does that make Trust and ROI free?
Rooms is described as free and open source for download. That does not establish a free production plan or limits for Trust and ROI. Request a written commercial answer covering access, usage, support, retention and exports before budgeting.
What is the safest first workflow for a small business?
A narrow, read-only support or information-drafting workflow using synthetic data, with a person reviewing every result, is a sensible starting point. Avoid permissions that change money, customer records or commitments until the evidence and controls justify them.
Conclusion
The strongest case for an AI monitoring platform is not that it produces more activity. It is that an owner can connect activity to verified outcomes, see the controls around the work and understand the full cost. Start with a human ledger if that is enough. If the workflow needs a broader inventory, testing and approval record, run a bounded pilot, measure equivalent-quality results and keep the decision reversible.
For Kenyan SMEs, disciplined evidence is the advantage. A cost-per-outcome calculation can expose hidden review effort; a trust checklist can expose excessive permissions; and a clear stop rule can protect customers before a small experiment becomes an uncontrolled dependency.
Need this built for your business?
Owners and operators who want a practical, human-reviewed starting point can speak with the UniqueTechCamp AI Solutions Desk ↗. You can book an appointment ↗ to discuss the workflow, or explore the workflow automation matching service ↗ for help choosing a proportionate next step.
Deploy An Autonomous AI Lead Gen System Today
We engineer high-converting web applications with integrated 24/7 WhatsApp qualification bots and multi-channel follow-up drips.
Related Strategy Articles
CrowdStrike AI Kill Switch: SME Team Reviewing an Agent Safety Dashboard
A practical SME playbook for reviewing CrowdStrike’s AI Kill Switch, testing agent containment safely, measuring trade-offs and checking Kenya eligibility.

Microsoft Agent 365 Business Analytics: An SME Readiness and Value-Validation Guide
Microsoft Agent 365 Business Analytics is in Frontier preview. Here is how Kenyan and East African SMEs can validate access, usage cost, value, privacy and readiness before buying licences for a dashboard.
Canva AI Controls: SME Design Review and Human Approval on a Laptop
A practical Canva AI Controls workflow for Kenyan and global SMEs: control settings, human review, asset provenance, measurements, costs and limitations.

UniqueTechCamp Desk
Online • Reply < 5 mins