
Gemini Decisions API: Product Listing Checks for Kenyan Shops
Explore Gemini Decisions API for Kenyan shop listing checks: verified token prices, product-image review, confidence limits and human approval.
UniqueTechCamp
Digital Solutions Team • UniqueTechCamp Engineering Unit
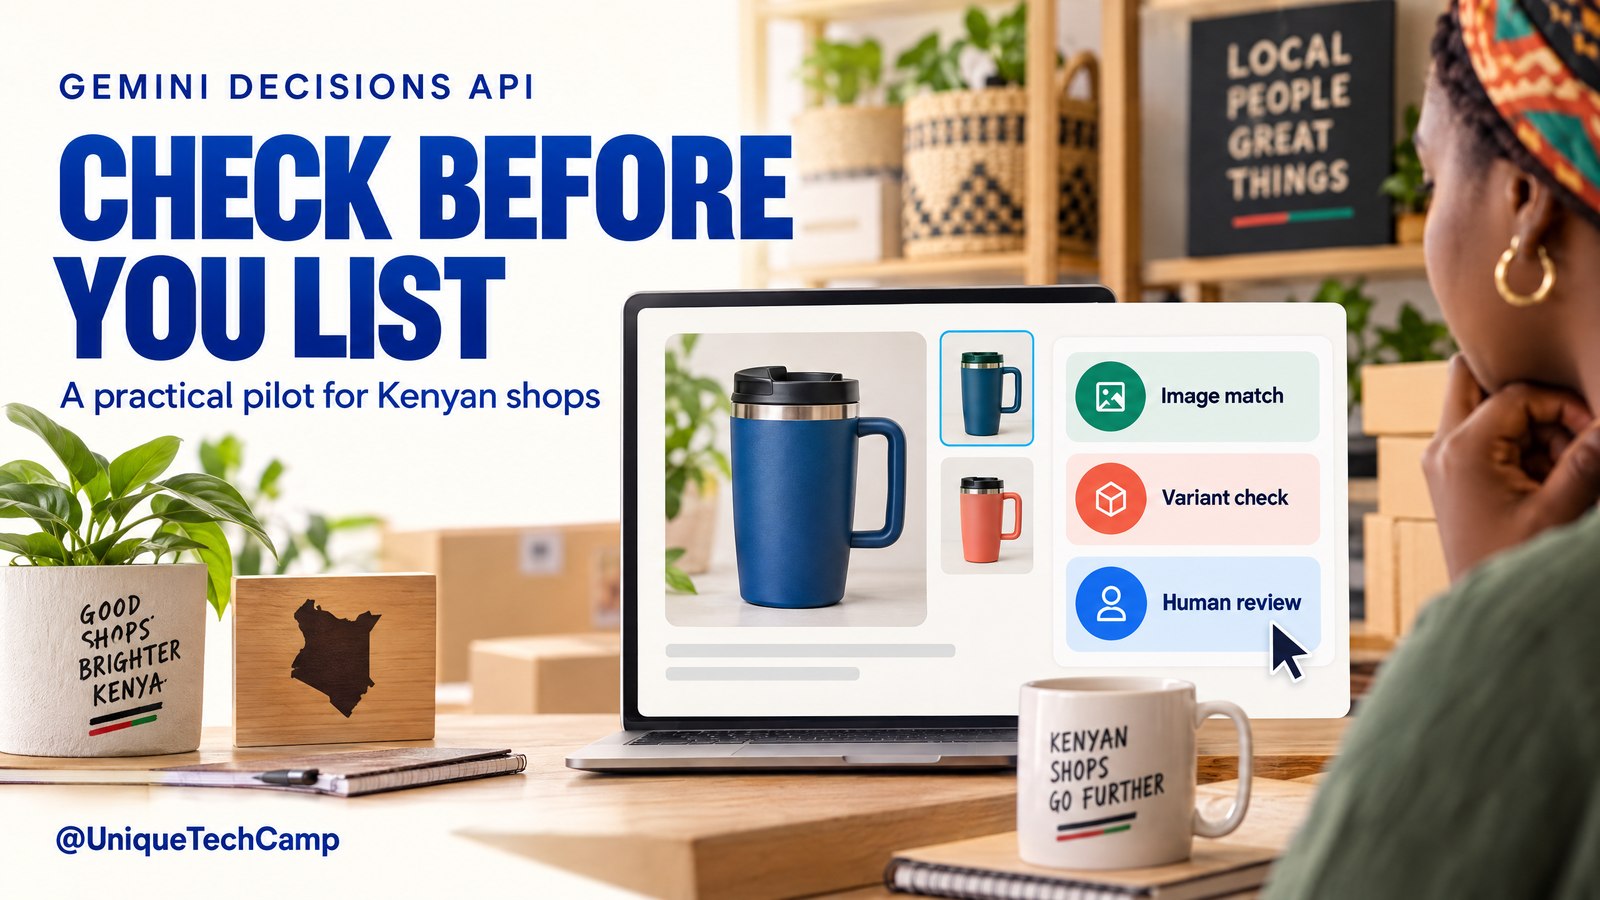
A customer opens a shop’s product page and sees a blue travel mug, a description of a red bottle and a pack size that appears to change between the headline and checkout. Nobody needs another chatbot to discover that problem. The business needs a repeatable check before the listing goes live, with someone responsible for resolving contradictions.
Google’s newly announced Gemini Decisions API is relevant to that narrower job. Rather than writing a description, it scores predefined questions against supplied information. For a Kenyan retailer, the useful experiment is not “let AI run the catalogue”. It is “help the catalogue editor spot specific inconsistencies, without changing a product or publishing anything automatically”.
This guide explains the actual release, current API costs and a proposed listing-check workflow. It is an implementation plan, not a tested client case study, and no conversion improvement or error-reduction figure is promised.
What Google launched, and what it did not
Google announced the Gemini Decisions API on 11 November 2026 ↗. Its Gemini Decision 1 model accepts text, images, audio, video and PDFs, evaluating up to 1,000 independent questions against a shared input. The supported question types are yes/no, a choice from predefined options, and an ordered scoring rubric. Answers contain probabilities and confidence information rather than generated paragraphs.
The live Gemini Decision model page ↗ identifies the model as gemini-decision-1. It does not support text generation, function calling, search grounding or the Batch API. It therefore does not write corrected product copy, browse for current supplier facts or publish a listing by itself. Those activities would require separate software and controls.
The distinction matters commercially. A model can judge whether the supplied photograph appears consistent with supplied text. It cannot establish that the warehouse actually has that variant, that a manufacturer’s claim is true or that a delivery promise can be met.
Start with one expensive-to-misunderstand product detail
Choose a small, manageable product family with recurring ambiguity: drinkware with several colours, storage boxes sold individually or in packs, or accessories with similar model names. Avoid beginning with medicines, regulated claims, safety-critical equipment or anything whose suitability requires qualified professional judgement.
Ask the catalogue editor and customer-service person which mismatch creates the most avoidable clarification or wrong-item complaint. That becomes the pilot’s first check. Do not begin by inventing hundreds of rules because the endpoint allows many questions. A handful of well-defined questions is easier to label, test and maintain.
Record the product identifier, proposed title, description, selected variant, approved source record and exact photograph being assessed. Keep stock status, approved prices and delivery rules in their authoritative business systems. If the source record is old or contradictory, classify the listing as needing investigation before asking a model to assess it.
Build an evidence pack, not a pile of supplier files
A useful input pack contains only the evidence for that listing: a clearly labelled approved product record, the proposed customer-facing text and the relevant image. Label each source by role and version. Otherwise the model may be unable to distinguish a draft marketing sentence from the business’s approved specification.
For a travel mug, the pack might identify the approved colour and capacity, then include the proposed page and image. A photograph of several mugs does not prove that the customer receives several mugs. Promotional accessories in a picture are not automatically included in the order. Write those distinctions into the review criteria.
Use ordinary validation rules for fields that should match exactly. Missing identifiers, duplicate identifiers, invalid dates and numeric comparisons are generally better checked in code. Google’s Decisions API guide ↗ specifically recommends comparing numbers, dates and durations in code. Save model evaluation for bounded interpretation where images and wording actually matter.
Turn a vague approval into independent questions
“Is this listing ready?” hides too many different judgements. Split it into checks with explicit instructions. For example: does the photograph visibly support the described colour; does the text clearly distinguish the selected variant; and does the description introduce an included accessory that the approved record does not support?
For a multiple-choice check, use defined outcomes such as “consistent”, “contradictory” and “insufficient evidence”. Describe when each applies. A separate evidence-sufficiency question is useful because a confident selection from an incomplete list can still be wrong. Do not make “consistent” the only convenient outcome.
For a rubric, define each level in observable language. “Unclear”, “partly specified” and “explicitly specified” need concrete criteria, not just labels. Keep the levels ordered and meaningful to the person who will review them.
Questions in one request cannot see each other’s answers. The application must combine results using ordinary rules. If an image is unreadable, the application should not treat another apparently positive image-related answer as proof that the listing passes.
Keep the first workflow in shadow mode
Run the checks alongside the existing editorial process without allowing the integration to write to the live shop. The editor still approves or rejects the listing. The model produces a separate review queue showing the product identifier, assessed version, question results, confidence values and the source pack.
The API does not generate a natural-language explanation. Do not display an invented explanation as though the model supplied it. The application can show the question, its criteria and the returned values; the reviewer records the actual reason for any correction. If another model generates commentary, label that as a separate, unverified aid.
A result should expire when the listing changes. If someone swaps the image or edits the pack description, rerun the relevant check rather than leaving an old approval badge attached to a new version. Preserve a link between each assessment and the exact input that produced it.
At UniqueTechCamp ↗, the useful scoping conversation is about that controlled handoff: which product record is authoritative, which checks are deterministic, what the AI may assess and which person can approve a correction. A new API is only one component of that workflow.
Confidence is not the same as a clean listing
Google describes confidence as an estimated probability that the top answer is correct. For a yes/no question, a high confidence value can accompany either yes or no. A confident “the image does not match” is a problem to resolve, not a pass. Read the answer and confidence together.
Set thresholds using labelled examples from your own catalogue. Include genuinely ambiguous photographs, several products in one image, supplier watermarks, mixed-language descriptions and cases where the approved record is incomplete. Separate the examples used to choose thresholds from those used to evaluate the resulting rules.
Do not copy a documentation example’s threshold and call it safe for your business. The cost of incorrectly clearing a mismatch differs from the cost of unnecessarily sending a clean listing for review. During the pilot, every proposed clearance should still receive human review, including high-confidence results.
Also test hostile supplier text such as a sentence demanding that the checker approve the listing. Treat such material as evidence to inspect, never as an instruction that changes the review rules. A supplied document cannot authorise publication or grant the integration more permissions.
What the API costs, and what the model price leaves out
The live Gemini Decision pricing section ↗ lists a paid input rate of USD 0.10 per one million input tokens across supported modalities. It generates zero output tokens, so there is no output-token charge. A free tier is listed, but that does not mean unlimited usage or identical data treatment.
Shared input is charged once per request, regardless of question count. Each question still adds tokens for its own instructions, criteria and formatting. Asking more questions is therefore not completely cost-free, and sending the same product pack again in a later request incurs another input charge. Context caching and the Batch API are not supported for this model.
Illustration only: if the API reports 2.5 million billable input tokens across the pilot, applying the published rate gives USD 0.25 in model input charges. This is arithmetic, not a forecast of how many products a shop can check. Image resolution, the evidence pack, question wording and repeated checks affect actual token usage.
Budget separately for integration, secure storage, monitoring, reviewer time, maintenance and applicable billing or tax effects. The cited price is in USD; it is not a local-currency, tax-inclusive quotation. Review recorded usage and the active account’s limits before increasing volume.
Check Kenyan access and data treatment before uploading
Google’s supported-regions page ↗ includes Kenya for Google AI Studio and the Gemini API. That is not a confirmation that a particular business account has activated billing, received a specific quota or completed every access requirement. Ask the implementer to demonstrate the intended project and model with approved test material.
Under the current Gemini API terms ↗, unpaid services may use submitted content to improve Google’s products, and human reviewers may process it. Google instructs users not to submit sensitive, confidential or personal information to unpaid services. Paid-service treatment depends on the account and project conditions described in those terms, not simply on whether an individual request happens to cost anything.
For paid services, Google says prompts and responses are not used to improve its products, but describes limited safety logging and possible transient storage or caching in countries where it or its agents operate. That is not a promise of zero retention or storage in Kenya.
Start with public or synthetic product material you are entitled to use. Remove customer names, order histories and private supplier contracts. Where personal data is involved, review the applicable obligations using the ODPC’s Kenyan regulatory framework ↗ and qualified advice. This checklist is not a legal opinion.
Measure review quality before claiming business impact
Have a knowledgeable person label a fixed evaluation set before examining the model’s output. Record which listings contain a genuine problem, which are clean and which cannot be decided from available evidence. Keep difficult examples instead of quietly excluding them to make the results look better.
Track missed mismatches, clean listings unnecessarily flagged, cases sent for clarification, reviewer agreement and time spent per completed review. Inspect the actual examples behind those measures. A single aggregate accuracy figure can hide a serious weakness in one product category or one type of photograph.
Commercial measures come later: repeated clarification requests about the same product, recorded wrong-variant complaints or relevant return reasons. Define the period and comparison group. Product mix, stock changes and staff training can affect those outcomes, so do not attribute every change to the model.
Pause the integration if it clears an important contradiction, loses its source record or attaches results to the wrong product version. A useful pilot can end with a decision not to automate. Better catalogue rules and cleaner product data may solve the problem more simply.
A practical handover the owner can approve
Before wider use, ask for a short operating note naming the source of truth, allowed inputs, question versions, review owner, failure queue and stopping conditions. The catalogue editor should be able to understand the outcome without opening a developer console.
Keep the API key server-side and restrict the integration’s shop access. The first version should need only the data required for checks, not permission to issue refunds, alter prices, change stock or fulfil orders. A timeout or exhausted quota should create a pending-review item, not an automatic pass.
Finally, demonstrate the workflow with one clean listing, one real contradiction, one unclear image and one service failure. Show how a reviewer rejects a suggestion, corrects the source data and reruns the check. That is a more useful acceptance test than watching a polished demonstration score an easy example.
Frequently asked questions
Can Gemini Decisions API rewrite and publish product descriptions?
No. Gemini Decision 1 returns bounded probabilities and scores, not generated product copy. Publishing requires separate shop software and permissions. Keep that permission out of an initial listing-check pilot and have an editor approve any change.
Does a high confidence score prove a listing is accurate?
No. It reflects the model’s estimated confidence in its selected answer against the supplied evidence and criteria. Missing evidence, confusing images or bad source records can still produce errors. Check which answer received the confidence and retain human review.
Is it available to Kenyan shops at a fixed local price?
Kenya is on Google’s general supported-regions list, but account, project, quota and billing checks still apply. The published model rate is USD 0.10 per one million input tokens, not a fixed implementation price or local tax-inclusive quote.
Can it confirm stock, payment or a supplier’s authenticity?
Not from a description or photograph alone. Use authoritative inventory and payment systems for operational facts. The model can assess supplied evidence against bounded criteria; it cannot prove a payment settled, a product is genuine or a manufacturer’s claim is lawful.
Conclusion: check the claim, preserve the evidence
The Gemini Decisions API offers a specific new building block: many bounded questions over shared multimodal input, with probabilities rather than generated prose. For a Kenyan shop, its value should be tested on a small catalogue problem that staff can recognise and judge.
Start with clear product records, independent questions, deterministic comparisons and human approval. Measure the mistakes it misses as carefully as the issues it flags. Expand only when the evidence shows that the review process is dependable and worth maintaining.
Need this built for your business?
If you own an online shop, bring one product family, approved product records, representative images and common listing mistakes to UniqueTechCamp’s AI Solutions Desk ↗. Use the appointments route ↗ to discuss a tightly scoped, human-reviewed pilot, or review the E-commerce Setup service ↗ for the storefront, catalogue and checkout work surrounding it. Ask for explicit data boundaries, acceptance tests, ownership and a separate implementation quotation before proceeding.
Deploy An Autonomous AI Lead Gen System Today
We engineer high-converting web applications with integrated 24/7 WhatsApp qualification bots and multi-channel follow-up drips.
Related Strategy Articles
CrowdStrike AI Kill Switch: SME Team Reviewing an Agent Safety Dashboard
A practical SME playbook for reviewing CrowdStrike’s AI Kill Switch, testing agent containment safely, measuring trade-offs and checking Kenya eligibility.

Microsoft Agent 365 Business Analytics: An SME Readiness and Value-Validation Guide
Microsoft Agent 365 Business Analytics is in Frontier preview. Here is how Kenyan and East African SMEs can validate access, usage cost, value, privacy and readiness before buying licences for a dashboard.
Canva AI Controls: SME Design Review and Human Approval on a Laptop
A practical Canva AI Controls workflow for Kenyan and global SMEs: control settings, human review, asset provenance, measurements, costs and limitations.

UniqueTechCamp Desk
Online • Reply < 5 mins